
In short
Web server monitoring should combine external availability checks with internal measurements of latency, HTTP errors, traffic, connections, CPU, memory, disk and dependency health. Alerts should fire only when a defined threshold lasts long enough to matter, then route to a named responder with enough context to diagnose the cause.
Key takeaways
- An external HTTPS check should validate expected content, not merely accept any
200 OKresponse. - Percentile latency such as p95 and p99 reveals slow requests that an average can hide.
- Generic 4xx errors should usually be investigated by route, while sustained 5xx errors can justify immediate escalation.
- A reliable alert combines user impact, a baseline or service objective, enough traffic and a sustained duration.
- Certificate warnings should begin well before expiry, with stronger escalation when automated renewal has not been confirmed.
Table of contents
- What should you monitor to know whether a web server is healthy?
- Which thresholds should trigger a warning or a critical alert?
- What should an external website check test?
- How do internal server metrics explain a slow or failing website?
- How do you find the actual cause instead of blaming the web server?
- How do you stop alerts from becoming noise?
- How do you check your web server today?
- What are the most common questions about web server monitoring?
- What should you do next?
What should you monitor to know whether a web server is healthy?
A healthy web server must be reachable, return the correct content quickly and retain enough capacity to handle the next increase in demand. Monitoring should therefore cover user-facing results and the internal conditions that explain those results.
The 2016 Site Reliability Engineering guidance on monitoring distributed systems identifies latency, traffic, errors and saturation as four core signals for user-facing systems. Website monitoring should add explicit availability, content correctness, DNS and certificate checks because a process can remain running while users receive the wrong page or cannot establish a trusted connection. (sre.google)
The six signals in one view

1. Availability and correctness
An availability check asks whether the service can be reached. A correctness check asks whether the service returned what a user needed.
Test DNS resolution, TCP connectivity, the TLS handshake, the final HTTP status and a stable marker in the response body. This catches failures such as an expired certificate, a broken redirect, a maintenance page, an empty template or a proxy returning a generic success page.
2. Latency
Measure both end-to-end response time from outside the hosting environment and server-side request duration. Keep successful and failed requests separate because a fast 500 response is still a failure.
Track p50 for the normal experience, p95 for the slow edge of common traffic and p99 for severe tail latency. The current OpenTelemetry HTTP metric conventions recommend http.server.request.duration as a histogram and support dimensions such as status code and low-cardinality route templates. (opentelemetry.io)
3. HTTP errors and failed transactions
Separate 5xx errors by status, route and upstream. A rising 500 rate may indicate application failure, while 502, 503 and 504 responses often point towards an unavailable, overloaded or slow upstream service.
Track 4xx errors as well, but do not page on the combined total by default. Under IETF RFC 9110, 4xx codes represent apparent client errors and 5xx codes represent server errors. A sudden rise in 401, 403, 404 or 429 responses can still reveal a broken release, incorrect security rule, missing route or rate-limit problem. (ietf.org)
4. Traffic and connections
Record requests per second, active connections, connection attempts, response size and network throughput. Break traffic down by route or workload class where possible, such as static files, product searches, logins, checkouts and API calls.
Traffic is context. Ten errors from 20 requests are urgent, while ten errors among a million requests require a different response. A sudden traffic fall can also indicate a DNS, routing, tracking or upstream failure even when the server reports low load.
5. Saturation and remaining capacity
Monitor CPU, available memory, swap activity, disk space, inode use, disk latency, I/O wait, network limits, worker utilisation, request queues, database connection pools and application thread pools. Use the resource closest to its real limit rather than assuming CPU is always the bottleneck.
Capacity trends matter before a hard limit is reached. A disk that will fill in two days deserves action even if it is only 82% full today. Rising p95 latency with growing queues is often a more useful early warning than waiting for CPU or memory to reach 100%.
6. Trust and dependencies
Monitor the certificate presented to users, its hostname coverage, expiry date and renewal status. Also check DNS records and the dependencies required for important requests, including databases, caches, storage, payment services, identity systems and external APIs.
The broader operating model, including who responds and what happens after an alert, is covered in the guide to server monitoring as a service.
A healthy web server is reachable, fast, correct, within capacity and able to maintain trust before users notice a fault.

Performance you can feel, backed by clients who depend on it. Read how our support and uptime create long‑term customer success.Power Your Business with Better Hosting
Which thresholds should trigger a warning or a critical alert?
Thresholds should reflect business impact rather than copying one universal CPU or response-time number. Begin with a measured baseline and service objective, then add a sustained duration, minimum traffic volume and clear escalation action.
The service-level objective guidance distinguishes measurable service indicators from the objectives set for them and warns that averages can hide tail latency. A useful policy might define the percentage of requests that must complete below a latency limit and the acceptable proportion of failed requests over a specific window. (sre.google)
A threshold needs four parts:
- Condition: What metric or user journey failed?
- Magnitude: How far has it moved from the baseline, objective or hard limit?
- Duration: How long must the condition remain true?
- Action: Does the event update a dashboard, create a ticket or page a responder?
A practical starter threshold matrix
The following values are a starting policy for a revenue-critical website, not an industry standard. Replace them with tested capacity limits, normal traffic patterns and the business's own tolerance for slow or failed requests.
| Signal | Warning | Critical or page | First response |
|---|---|---|---|
| External availability | Two consecutive failures from one location | Failures from two or more locations for two minutes, or a critical transaction fails | Confirm DNS, TLS and recent changes before restarting services |
| p95 response time | Above 1.5 times the same-hour 28-day baseline for 10 minutes | Above twice the baseline for five minutes, or the stated SLO is breached | Compare server duration, queues and dependency latency |
| 5xx error rate | Above 1% for 10 minutes with at least 100 requests | Above 5% for five minutes, or a key journey fails | Group errors by route, status and deployment version |
| 4xx error rate | More than 50% above the normal route-level rate for 15 minutes | Page only when a known-good request or critical route fails | Check authentication, redirects, WAF rules, routes and rate limits |
| Active connections or workers | Above 70% of a tested limit for 15 minutes | Above 85% with rising latency, queues or errors | Find slow requests, stuck workers and connection leaks |
| CPU | Above 80% for 15 minutes | Above 90% for 10 minutes with user impact | Identify the process, route or scheduled task using CPU |
| Available memory | Below 15% for 15 minutes, or swap use is rising | Below 5%, an out-of-memory event, or repeated process restarts | Check process growth, cache behaviour and recent releases |
| Disk or inodes | Below 20% free, or forecast to fill within 14 days | Below 10% free, write failures, or forecast to fill within 48 hours | Find growing logs, backups, uploads and temporary files |
| TLS certificate | 30 days remaining | 14 days if renewal is unconfirmed, emergency escalation at seven days | Confirm the certificate on the public endpoint and test renewal |
| Content or DNS correctness | Wrong content or record mismatch in two checks | Confirmed from multiple locations or affecting a critical hostname | Compare deployment, cache, proxy, DNS and origin configuration |
Do not page solely because CPU reached 81% for one minute. Short spikes may be normal. Page when a sustained capacity signal predicts failure or appears beside user-facing latency, error or availability impact.
Error-rate alerts also need a denominator. A 10% error rate based on ten requests is one failure, while 10% of 10,000 requests is a major incident. Set a minimum request count, but add a separate synthetic check so a low-traffic checkout, form or API is not ignored.
Use relative thresholds for metrics that follow daily or weekly patterns. Compare Monday morning with previous Monday mornings, not with a quiet overnight average. Use hard thresholds for resources with fixed limits, such as disk space, inode capacity, worker pools and certificate expiry.
A useful threshold combines user impact, a baseline or objective, enough traffic and a sustained duration.
What should an external website check test?
An external check should reproduce the parts of a request that the hosting server cannot verify by looking at itself. It should prove that a user can resolve the hostname, establish a trusted connection and receive the expected response.
A useful external monitor checks:
- The expected DNS record resolves from more than one location.
- Port 443 accepts a connection.
- The TLS handshake succeeds with the correct hostname.
- Redirects finish on the intended canonical URL.
- The final status code is allowed for that endpoint.
- The response contains a stable content marker.
- Total response time stays inside the relevant objective.
- A critical transaction, such as login or form submission, works without creating live orders or messages.
A dedicated health endpoint should be fast and safe. A shallow liveness endpoint can confirm that the application process is accepting requests. A deeper readiness endpoint may check essential dependencies, but it should use cheap operations and strict timeouts so the monitor does not create extra load during an incident.
Do not rely on the homepage alone. A cached homepage may remain available while uncached product pages, search, login, checkout or an API fails. Select a small group of URLs and transactions that represent how the business earns revenue or receives enquiries.
Certificate monitoring deserves its own alert. As of September 2026, the CA/B Forum Baseline Requirements limit publicly trusted TLS server certificates issued from March 15, 2026 until before March 15, 2027 to a maximum validity period of 200 days. Shorter validity increases the value of tested renewal automation and early expiry warnings. (cabforum.org)
Let's Encrypt's July 2026 monitoring guidance also identifies expiration notifications and unwanted issuance as useful certificate-monitoring functions. Check the certificate presented by the public endpoint because a proxy or edge service may present a different certificate from the origin server. (letsencrypt.org)
External monitoring should prove that a real request can resolve, connect securely and return the right content.
Host your website with our 5-star rated, cPanel website hosting plans.
Super fast servers, with security included and hosted in your choice of Australian Data Center.
View cPanel Plans
How do internal server metrics explain a slow or failing website?
Internal metrics show which resource or component changed when the user-facing signal moved. They are most useful when request rate, latency, errors, queues and resource use can be viewed on the same timeline.
Operating-system capacity
Track CPU by process, available memory, swap in and out, filesystem space, inode use, disk latency, I/O wait, network throughput and dropped connections. Prefer available memory over raw used memory on systems that use spare RAM for filesystem caching.
Watch the direction as well as the level. Slowly declining free disk, steadily growing process memory or rising I/O wait can reveal trouble long before a hard outage.
Web-server activity
Collect requests per second, active connections, accepted and dropped connections, busy and idle workers, request queues, connection states and response codes. A difference between accepted and handled connections, exhausted workers or a queue that grows while throughput stays flat can reveal saturation.
The current Apache HTTP Server 2.4 documentation lists serving and idle workers, requests per second, bytes per second, CPU use and active requests among the available status information. Protect the status endpoint because detailed request and client data should not be publicly exposed. (httpd.apache.org)
The NGINX status documentation exposes active connections, accepted and handled connections, request totals and reading, writing and waiting connection states. These counters become much more useful when graphed as rates and compared with configured worker limits. (nginx.org)
For platform-specific investigation, use linux server monitoring to examine operating-system pressure. Windows-hosted applications may also need our guide to iis server monitoring and a separate evaluation of windows server monitoring software.
The IIS monitoring API documentation includes CPU, memory, HTTP request, connection, cache and disk data for the server, sites and application pools. Application-pool state and per-site measurements help separate a single failing application from a host-wide capacity problem. (learn.microsoft.com)
Application and dependency measurements
Add route-level duration, status code, database duration, cache hits and misses, queue depth, thread or connection-pool use and outbound API duration. A web server may be healthy while every request waits for a database lock or slow third-party response.
Attach a deployment or configuration-change marker to the same timeline. If 5xx errors begin immediately after a release, that context can save more time than another generic dashboard panel.
Internal metrics explain why the site is failing only when they are read beside traffic, latency and errors.
How do you find the actual cause instead of blaming the web server?
Start at the user's failed request and follow every handoff until the first abnormal signal appears. The visible error may come from the web server even when the original fault sits in DNS, a proxy, the application, a database or an external service.
The request path to inspect
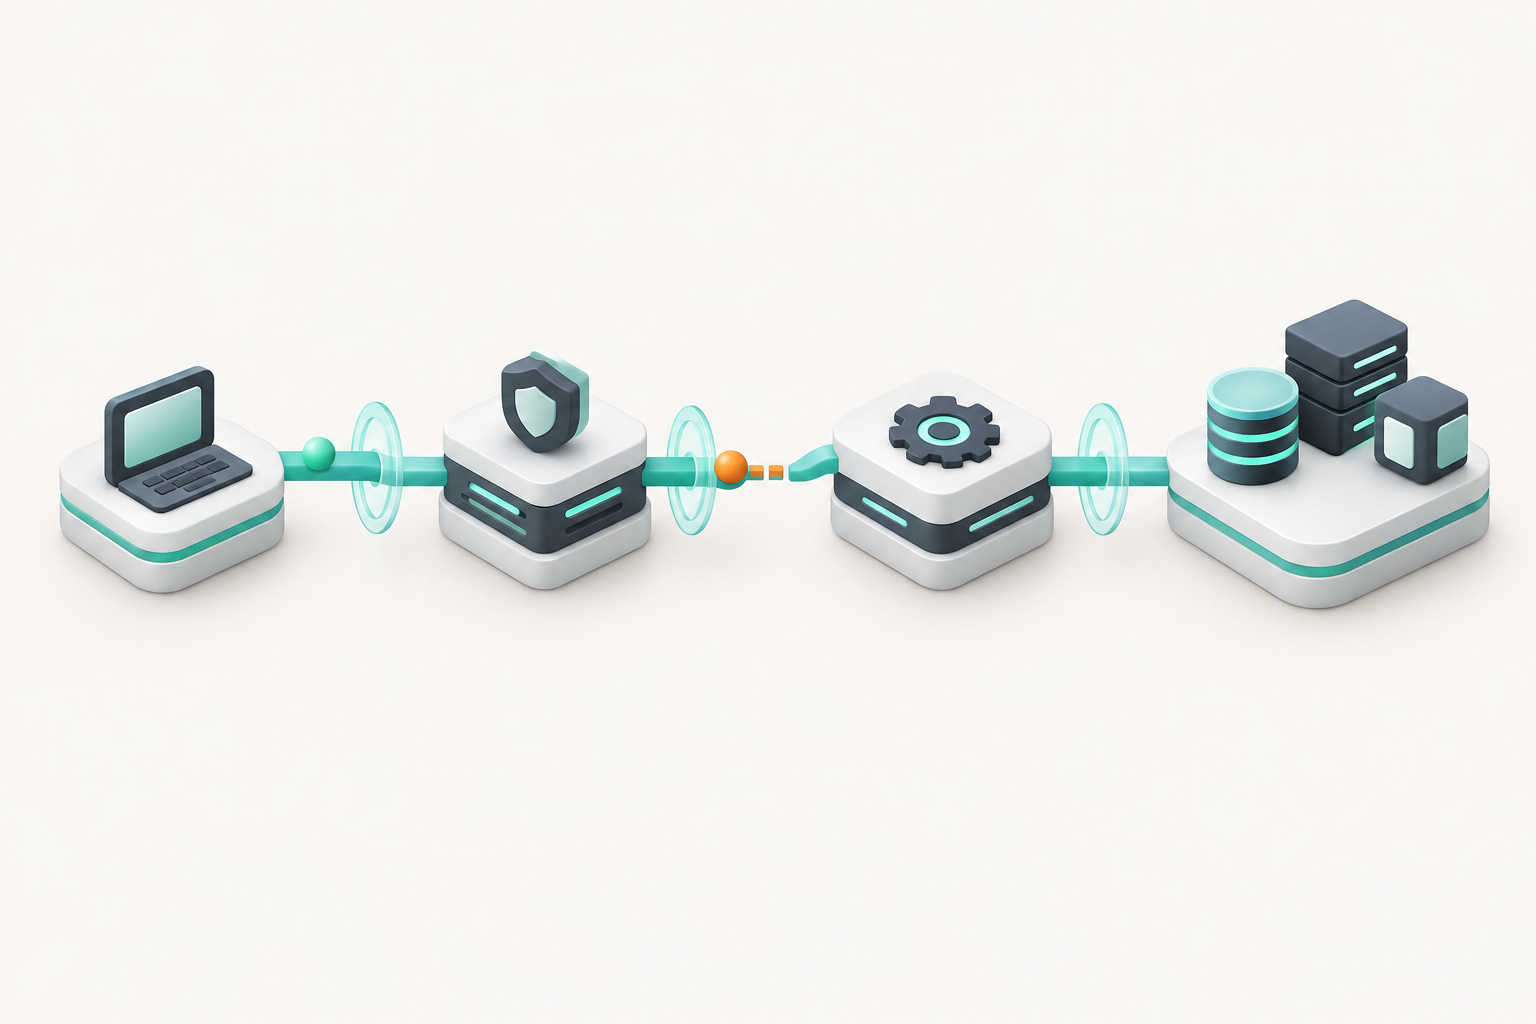
A typical request passes through DNS, TLS termination, an edge or proxy, a load balancer, the web server, application code, a cache or database and any external APIs. Monitor each boundary with a small set of shared fields: timestamp, request or trace identifier, route, status, duration and destination.
Use these combinations to narrow the search:
- External checks fail while the host is healthy: Inspect DNS, certificate delivery, routing, firewalls, proxies and load balancers.
- Latency rises while CPU remains low: Check database duration, locks, storage latency, connection pools, DNS lookups and external APIs.
- Latency, queues and CPU rise together: The service may be reaching processing capacity or receiving a costly traffic pattern.
- 5xx errors start after a deployment: Compare the failing route, application logs, configuration changes and dependency versions.
502or504responses rise: Check whether the upstream application is refusing connections, restarting or exceeding a timeout.- Memory climbs until the process restarts: Investigate leaks, unbounded caches, large requests and workload changes.
- Only one monitoring location fails: Inspect regional DNS answers, routing, edge configuration and network reachability before restarting the origin.
- The response is fast but contains the wrong content: Check caches, deployment targets, virtual-host routing and maintenance-page rules.
Keep logs and metrics on synchronised clocks. A five-minute clock difference can make a deployment appear to occur after the failure it caused. Retain enough history to compare the incident with a normal period that had similar traffic.
Do not restart first unless service restoration requires it. A restart may clear the queue, memory growth or stuck process while also destroying the evidence needed to prevent the next incident. Capture process state, recent logs, active requests and resource use before recovery where time permits.
Trace the full request path, because the web server is often where a dependency problem becomes visible rather than where it begins.
How do you stop alerts from becoming noise?
An alert should identify a condition that requires a specific response from a specific owner. Dashboard data that is interesting but not actionable should remain a dashboard signal or create a lower-priority ticket instead of waking someone.
Use three practical levels:
- Page now: Multi-location outage, failed critical transaction, sustained high 5xx rate, write failure, imminent certificate expiry or capacity exhaustion with user impact.
- Investigate during the current shift: Significant latency increase, growing queue, memory or disk forecast approaching a limit, unusual route-level 4xx errors or failed renewal automation.
- Review as a trend: Slow capacity growth, one-location anomalies, non-critical traffic changes and isolated errors below the minimum volume.
The alert workflow

First, require the signal to remain abnormal long enough to filter a harmless spike. Next, confirm whether users or a critical transaction are affected. Route the alert to the service owner, then escalate only if the alert remains unacknowledged or the impact grows.
Each alert should include:
- The affected hostname, route, service and environment.
- The measured value, threshold, baseline and duration.
- Request volume or sample size.
- The locations or instances reporting failure.
- Links to the relevant graph, logs and runbook.
- The most recent deployment or configuration change.
- The expected owner and escalation path.
Use separate warning and recovery thresholds when a metric hovers around a boundary. For example, a warning might open above 80% worker use and close only after it remains below 70%. This gap prevents repeated open and close notifications.
Group alerts that share the same likely cause. A database outage may produce hundreds of route-level 500 errors, but the responder needs one incident with supporting symptoms, not hundreds of independent pages.
Schedule maintenance windows for planned restarts and releases. Keep collecting data during the window, but suppress notifications that have no response value. After maintenance, confirm that synthetic checks, error rates and queues returned to normal rather than assuming the change succeeded.
An alert is useful only when it names the impact, lasts long enough to trust and reaches an owner who can act.
Register your new domain name at competitive market prices including free domain add-ons like privacy, DNS Hosting, Custom Nameservers and Forwarding.
Always the best price and no nasty renewal price hikes.
Register A Domain Name
How do you check your web server today?
Begin with the smallest monitoring set that can detect user impact and explain the likely cause. One external check and five internal signal groups are more useful than a large dashboard that has no thresholds, owners or tested notifications.
A 30-minute setup sequence

- List critical journeys. Choose the homepage plus the login, enquiry form, checkout, API or other transaction whose failure would cost the business first.
- Create external HTTPS checks. Test DNS, TLS, final status, expected content and response time from more than one location.
- Collect the first internal signals. Add request duration, 5xx rate, request rate, active connections or workers, CPU, available memory and disk capacity.
- Set warning and critical rules. Use the starter matrix, then replace its values with the site's objective, baseline and tested limits.
- Test the response path. Trigger a safe test alert, confirm that the intended person receives it and verify that its dashboard and runbook links work.
Run a manual check before assuming the monitor is wrong. Resolve the hostname, inspect the presented certificate, request the health URL and compare the result from a network outside the server environment. A browser tab alone is not enough because browser caches, local DNS and existing connections can hide a fault.
When selecting software, require external checks, percentile latency, status and route grouping, resource metrics, certificate warnings, maintenance windows, alert delays and notification channels the response team actually uses. A simple web dashboard is helpful, but only if it exposes the evidence needed to make a decision.
Start with one external check and five internal signals, then test the alert path before adding more data.
What are the most common questions about web server monitoring?
The best monitoring arrangement depends on the site's architecture, traffic and business risk. These answers focus on the capabilities that remain useful across different hosting platforms and monitoring tools.
What is the best tool for monitoring servers?
The best server-monitoring tool is the one that covers external availability, internal resources, logs and alert routing without creating noise. For a revenue-critical site, require percentile latency, route-level errors, certificate expiry, dependency checks, configurable alert durations and a clear path to the person responsible for response.
What is the best web monitoring software?
The best web monitoring software checks HTTPS from several locations, validates expected content, measures percentile latency, tracks certificates and connects failures to internal metrics. It should also support maintenance windows, alert delays, route-level grouping and clear escalation. A polished dashboard matters less than accurate checks and actionable notifications.
How do I check my web server?
Check a web server from both sides. From outside, test DNS, TLS, HTTP status, expected page content and response time. From inside, inspect 5xx errors, request rate, active connections, worker or queue pressure, CPU, available memory, disk space and dependency latency. Then compare the results with recent changes.
What is the best free monitoring tool?
The best free monitoring option is a combination, not a single dashboard: one external HTTPS checker, one internal metrics collector and centralised logs. Free plans can be enough for a small site, but check polling intervals, retention, alert channels, certificate monitoring, multi-location coverage and limits before relying on them for critical revenue.
The best tool is the one that sees user impact, explains the cause and reaches the person who can act.
Experience Microsoft 365 Business Standard for free for 30 days.
Up to 25 users with full access to email, OneDrive and Teams. Includes full versions of desktop apps of Outlook, Word, Excel, PowerPoint and more.
Try Microsoft 365
What should you do next?
Choose one critical URL or transaction and write down its acceptable availability, p95 latency and error rate. Add a warning, a critical condition, an owner and a first-response note, then trigger a safe test to confirm that the notification reaches the right person.
Businesses that want monitoring handled as part of a managed security and protection approach can review UpTime Networks' IT monitoring service.
Start with the failure that would cost the business first, and make sure its alert reaches someone before a customer has to report it.


